


Changing Identifiers/paths when extracting text from pdf
Hello,
Iam a bit new to adobe.
Iam working on a project to read out text/table information from pdf, extract it via python-SDK and use the extracted information to create new data sets in an external system.
PDFs are created via web forms from adobe. I want to retrieve these documents using the v6 sign api.
Currently Iam working with local pdf files.
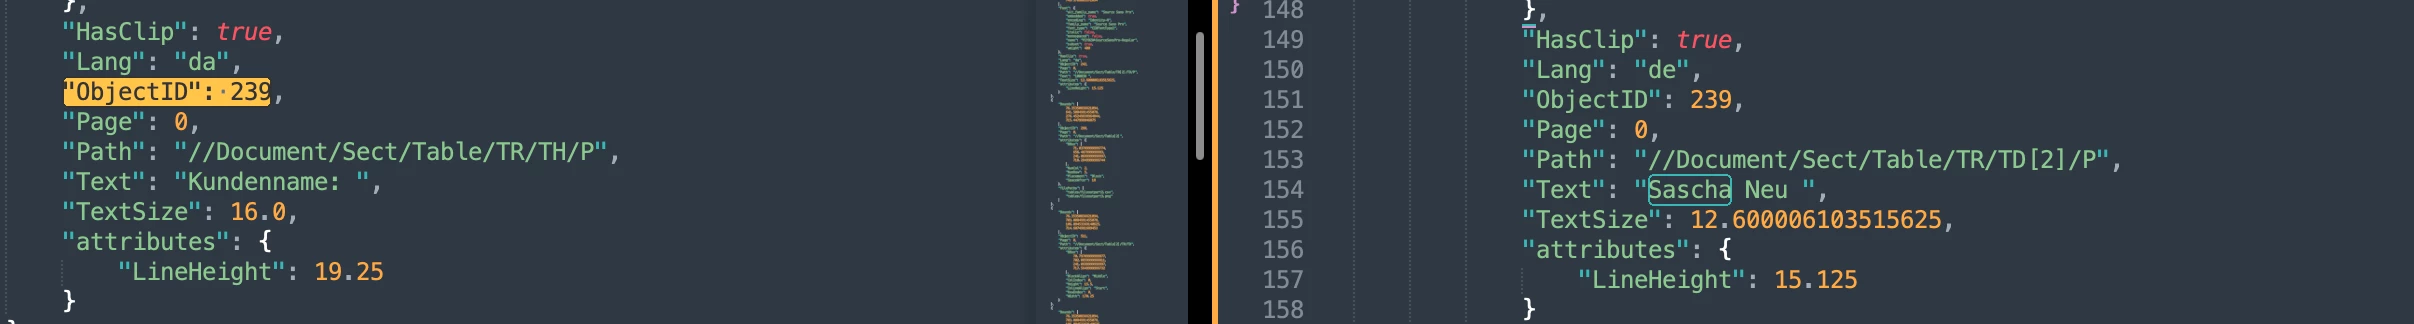
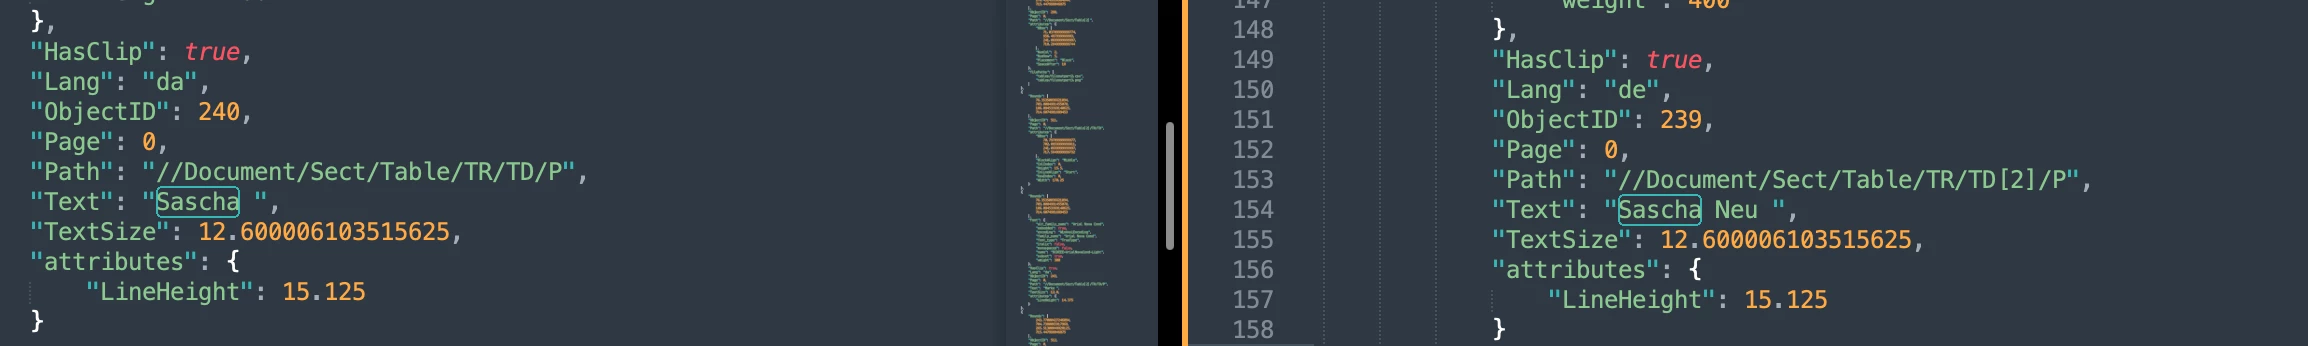
I have tried out plenty of standard-functions, however they all seem to have the same problem. I don't get consistent identifier for objects/paths, if some of the optional form-content won't be filled.
Example:
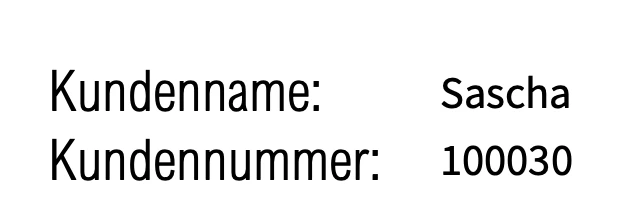
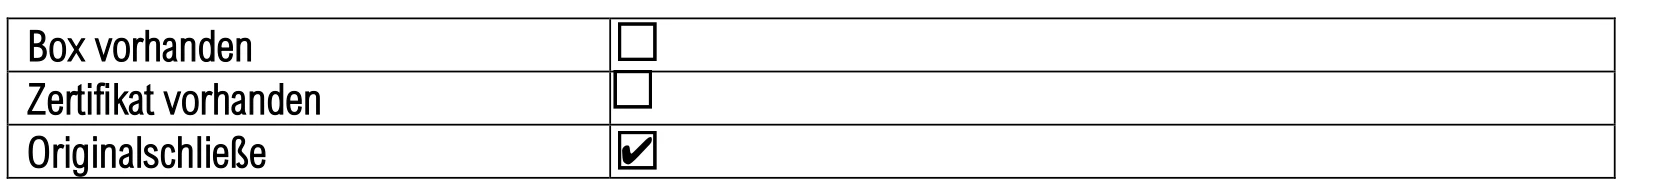
We are asking for customer names in the formular. If one of the optional check boxes aren't ticked I do receive different object-IDs. Also the provided path-information is differentiating.
Additionally I expected just to have a NULL-value or something else if an optional content is not provided. However, It won't get listed at all.
Is there a function that avoids this behavior?
Regards
Patrick
 AdChoices