Question
Missing font leads to missing characters at the Extraction API output
When extracting text from Page 59 (zero based counting) at the following PDF, The word 2008 is extracted as unknown characters:
"Text": "WESTERN UNION Annual Report "PDF file
When watching the PDF with Acrobat Reader, it looks ok:
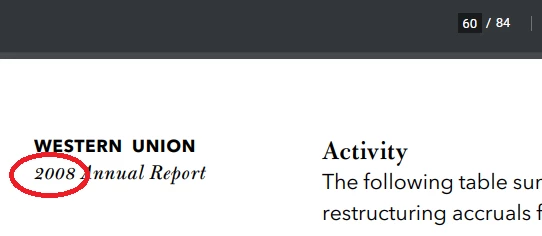
I tried with PDFBox, and got the following error for these characters:
No Unicode mapping for twoalt (2) in font HGLLLJ+BulmerMT-ItalicAlt
Any help with that would be highly appriciated !!!


 AdChoices