


Participant
Mar 22, 2024 10:57 PM UTC
Question

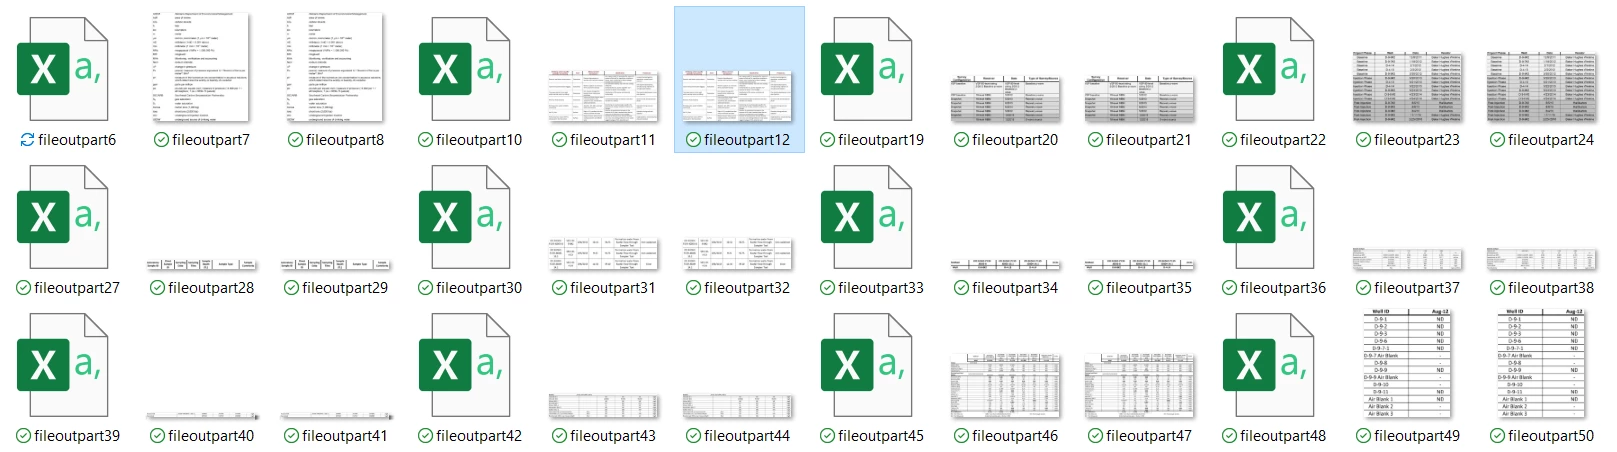
PDF Services API Extract Table returning Screenshots and not CSVs

I'm just starting work with the PDF services API in my python project, and I'd successfully extracting elements from a PDF, but only a portion of the extracted tables are in CSV files (the rest being screenshots). Are there limitations to extracting tables into CSV files and the screenshots are a backup, or how can I try to get exclusively CSVs out of my PDF so I can work with that data?
 

This topic is closed to new replies. Start a new post to keep the conversation going.

1 reply

Participant
Mar 22, 2024 11:05 PM UTC

Posting my code for PDF Extract Options in case that's helpful


            # Build ExtractPDF options and set them into the operation
            extract_pdf_options: ExtractPDFOptions = ExtractPDFOptions.builder() \
                .with_elements_to_extract([ExtractElementType.TEXT, ExtractElementType.TABLES]) \
                .with_element_to_extract_renditions(ExtractRenditionsElementType.TABLES) \
                .with_elements_to_extract_renditions([ExtractRenditionsElementType.TABLES,
                                    ExtractRenditionsElementType.FIGURES]) \
                .with_table_structure_format(TableStructureType.CSV) \
                .build()
            extract_pdf_operation.set_options(extract_pdf_options)

            # Execute the operation.
            result: FileRef = extract_pdf_operation.execute(execution_context)
Translate